Multi-touch attribution (MTA) shares credit for a conversion across the interactions your systems recorded before it. An attribution model is the rule that decides how that credit is shared. Changing the model changes the report, not what the customer did, so pick the model for a specific question and check the data underneath it first.
What is multi-touch attribution?
Multi-touch attribution assigns credit to more than one interaction before a defined conversion. That conversion might be a form submission, a purchase or a won deal. Choose it on purpose. Those outcomes describe different stages of the business, and they come from different systems with different dates.
A customer may click an ad, come back through search, read a case study, follow an email link and then book a demo. If your systems recorded those interactions and you can reliably connect them, they form one path. A first-touch report gives all the credit to the ad. A last-touch report gives it all to the email. A multi-touch model spreads it across the path according to a rule or a statistical method.
The path stays the same. Only the allocation changes. That is the most useful thing to understand about attribution models: each one is a different view of the same recorded journey, and each one quietly rewards a different stage of it.
Two limits apply to every model:
- It only sees what was recorded and connected. A model cannot give credit to a touch the dataset excludes, or to an interaction that happened somewhere you don’t track.
- It describes, it doesn’t prove. Attribution shows which interactions appeared before a conversion. It does not establish that each one caused it.
Attribution models compared
Single-touch models give all the credit to one interaction. Multi-touch models split it across several. Rule-based models are a good starting point because anyone on the team can see how the credit was assigned. Data-driven models estimate the weights from data, so they depend on coverage, training data and the platform’s method.
| Model | Type | Who gets credit | Best for | Blind spot / what to question |
|---|---|---|---|---|
| First touch | Single-touch | All credit to the first eligible interaction | Demand gen, new markets: what starts the recorded journey | Ignores everything that closed the deal |
| Last touch | Single-touch | All credit to the final eligible interaction | Short, simple sales cycles | Over-credits brand and bottom-funnel activity |
| Linear | Multi-touch, rule-based | Equal credit to every eligible interaction | Long, multi-touch journeys | Treats a glance like a sales demo. Repeated touches can inflate a channel’s share |
| Time decay | Multi-touch, rule-based | More weight to interactions closer to the conversion | Considered B2B purchases | Still under-credits early discovery. Does the decay rate fit your buying cycle? |
| Position-based (U-shaped) | Multi-touch, rule-based | Extra weight to the first and last touch. A common split is 40/20/40: 40% each to the first and last touch, 20% shared by the touches in between | Journeys where both discovery and the final touch matter | Why should those positions get that weight? |
| Data-driven | Multi-touch, statistical | Weights estimated from the available data | When the platform’s documented model fits the question | Method and inputs differ by platform. What coverage and validation support the result? |
These are analytical choices, not a ranking from bad to good. If a channel’s value changes sharply when you switch models, investigate that sensitivity before treating either number as a budget instruction.
Whichever model you use, write down the lookback window and the rules for direct traffic, repeat touches and channel classification. A model name without those details isn’t enough to reproduce the report.
How linear attribution calculates credit
A linear model divides the conversion’s credit equally among the eligible touches in the lookback window. With four eligible touches, each gets a quarter. If the outcome is a deal, each touch gets a quarter of the deal value. “Eligible” is doing a lot of work here: the lookback window, how repeat visits are counted and whether direct traffic is included all change the answer.
Deterministic vs probabilistic attribution
This is a separate question from the model. It’s about how the touches got connected to the outcome in the first place.
- Deterministic connections rely on an identifier with a documented meaning in your sources. An event ID identifies an event. A CRM contact ID connects a known person to a deal. You can point to the record that links them.
- Probabilistic connections are inferred or estimated. Some platforms fill gaps with modeled data when they can’t observe an event directly. Google documents that modeled key events may appear in eligible GA4 reports.
Keep the two apart. Label modeled output, document the method, and don’t mix estimates into a total that readers assume is observed. A model built on probabilistic links isn’t wrong, but the report should say which parts are matched and which are estimated.
Even deterministic IDs have limits. A contact ID doesn’t necessarily represent every device a person used, or every person in a buying group.
Which attribution model to choose
Stop looking for the true model. Pick the lens that fits the decision, and be honest about what it can’t see.
- Growing awareness or entering a new market? Lean first-touch.
- Short cycle, one or two touches? Last-touch is fine, and simpler.
- Long B2B journey you’re trying to understand? Linear or time-decay.
- Does a platform’s documented data-driven method fit the question? Compare it with a simpler rule and note the assumptions.
- Reporting to a CFO? Anchor everything to blended results and revenue.
Smaller teams don’t need complex software to start. GA4, ad platform data, CRM data and a clear reporting rule are enough for a first version. If you’re on GA4 without a warehouse, GA4 attribution reports without BigQuery covers what the built-in reports can and can’t do. Teams that need more control usually move MTA into BigQuery or another warehouse.
Start with one reporting question
A manageable first question: which recorded campaign interactions came before qualified leads this quarter? Agree on the lead definition and the date field, then build around those choices.
- Define one conversion outcome and reporting period.
- List the sources that record the relevant interactions and outcomes.
- Check campaign tagging, timestamps, duplicates and missing identifiers.
- Choose a simple model and write down its eligibility and lookback rules.
- Compare sample journeys and totals with the source records.
- Review the result beside another model and record unexplained differences.
Once that report is useful, extend it to other outcomes or sources. Adding more models before you’ve validated the first one usually just creates more numbers to explain.
How to implement multi-touch attribution
The hard part of an attribution system is usually the data pipeline before the model. Events arrive late, identifiers change, and CRM outcomes use different dates. Build a system that makes those differences visible before it assigns any credit. The sections below follow the decisions in that pipeline: the outcome definition, the layers, identity rules, reconciliation and upkeep. Worked BigQuery queries and Maven prompts follow in the query examples.
Define the conversion before the schema
Choose the business outcome the model will explain. A form submission, a qualified lead, a booked sale and recognized revenue use different source records and dates. Name the source of record and the field that decides whether an outcome is in the report.
Then define the unit of credit. If the model allocates deal value, decide how it handles reopened deals, partial refunds, currency and later corrections. Those choices affect the result as much as the weighting formula does.
Build the pipeline in layers
Keep the pipeline in layers, so a disputed total can be traced back to source records. Raw ingestion should keep what arrived. Normalization and attribution rules belong in transformations you can inspect and rerun.
| Layer | Responsibility | Useful evidence |
|---|---|---|
| Raw ingestion | Keep source records and arrival times | Source IDs, extraction timestamps, refresh logs |
| Normalization | Standardize types, timestamps, currencies and channel fields | Mappings and excluded-record counts |
| Identity and paths | Connect eligible interactions to outcomes | Join keys, match rules, unmatched records |
| Attribution | Apply versioned eligibility and credit rules | Model version, lookback window, allocated credit |
| Reporting | Show the agreed metrics and their limits | Definitions, data-through dates, reconciliation notes |
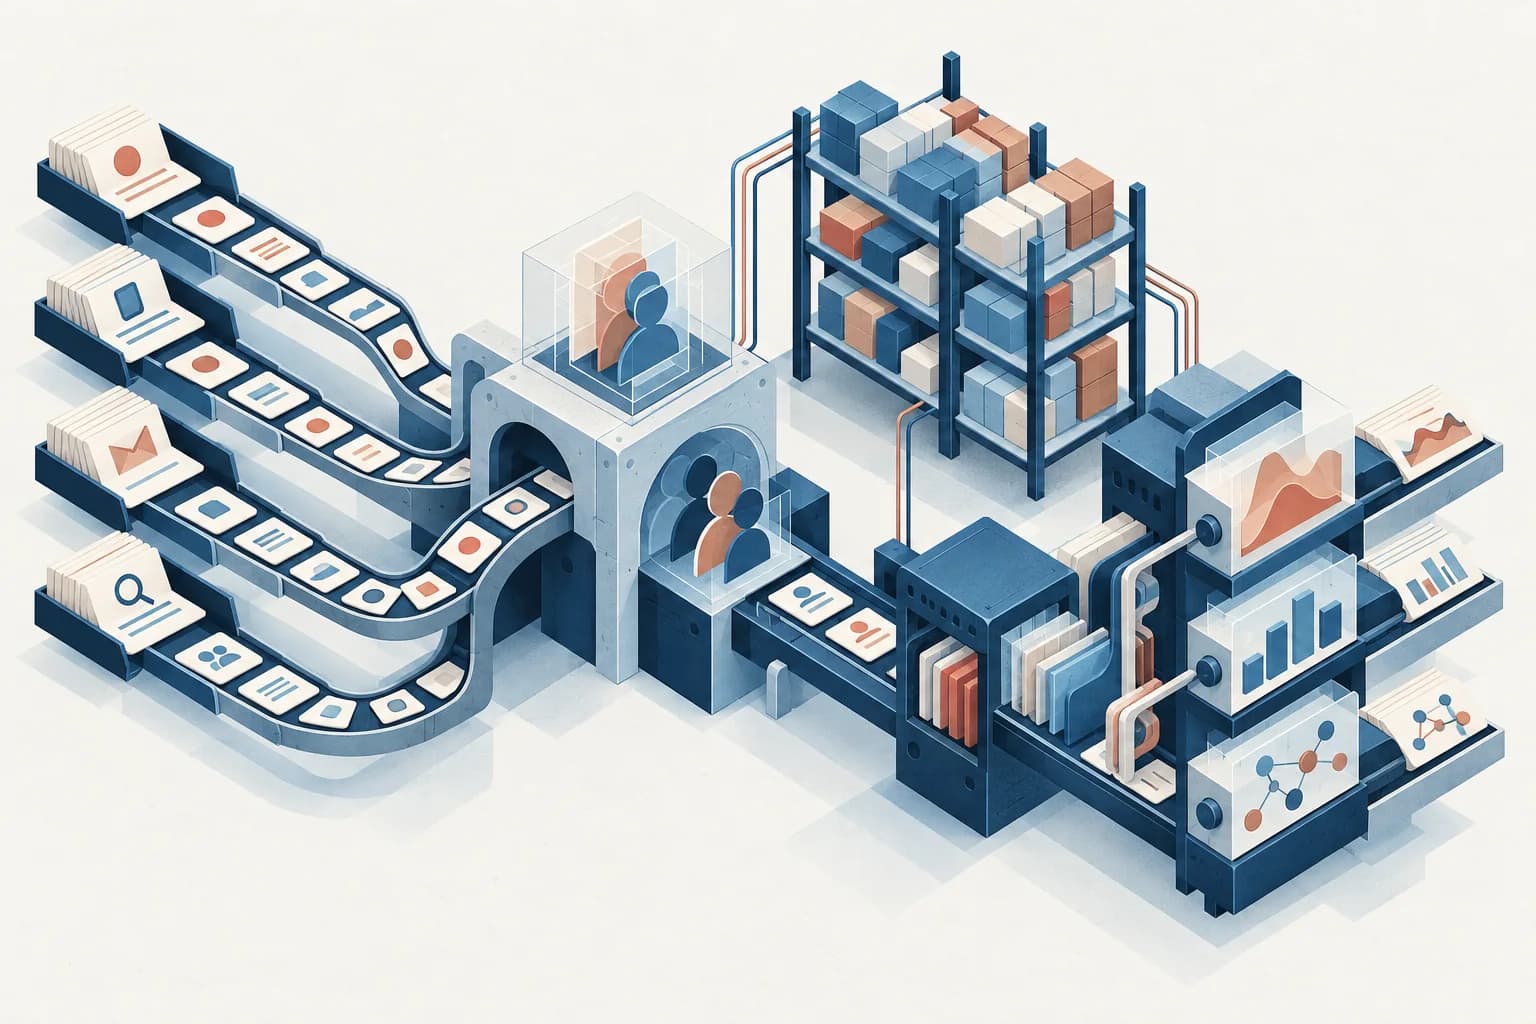
A warehouse can hold these layers without making them trustworthy. The value comes from explicit rules and checks, not from moving the same unexplained spreadsheet logic into SQL.
Build paths with defensible identity rules
At minimum, a path needs interactions, timestamps and a defensible connection to the outcome. Start with identifiers that have a documented meaning in your sources, and record which method made each connection. Keep deterministic matches separate from probabilistic assumptions.
Leave unresolved outcomes visible. A missing join tells you about coverage. It isn’t a reason to invent a match or force unrelated records together to make a complete-looking journey.
Consistent campaign tagging helps explain acquisition. CRM stage changes and deal dates help explain what happened later. You need both, and neither replaces the other.
Consent and destination restrictions still apply when processing moves to a server or a warehouse. Only collect and use identifiers for permitted purposes. Review what leaves each system, including URLs, form values and properties that get attached automatically.
Reconcile the allocation before using it
For each eligible outcome, the model’s fractional credits should add up to the intended total. Across outcomes, allocated value plus any value you’ve explicitly left unassigned should match the source total under the same definitions.
Look at individual journeys as well as totals. A many-to-many join can duplicate value and still produce a plausible chart. Test repeated events, multiple conversions, missing identifiers and late updates on purpose.
- Enforce uniqueness at the intended event and outcome grain.
- Check that eligible touches come before the outcome and fall inside the lookback window.
- Verify that credit sums correctly at both the outcome and reporting levels.
- Show unmatched records and changes in coverage.
- Compare a sample of paths with the original source records.
- Record model versions and review the effect of rule changes before release.
Set a refresh cadence the decision needs
A monthly budget review may not need real-time attribution. A daily operational workflow may need fresher data, but the CRM upstream could still update later. Set a cadence that fits both the decision and how the sources behave.
Plan for late events and corrected outcomes. Rerun the affected periods, keep enough history to explain what changed, and tell report readers which periods are still settling.
Keep the model maintainable
Give one person ownership of source changes, definitions and model releases. Keep the tests and documentation next to the transformations, so a new maintainer can see why each rule exists.
When a model changes the channel story, show the comparison and the reason. A result that differs from last-click reporting isn’t automatically more accurate. It’s another view, and it needs evidence and an explanation.
Platform-specific builds
- GA4 and BigQuery: GA4 multi-touch attribution with BigQuery turns the export into sessions and builds position-based and time-decay models in SQL.
- GA4 without a warehouse: GA4 attribution reports without BigQuery.
- HubSpot: multi-touch attribution in HubSpot.
- Salesforce: multi-touch attribution in Salesforce.
For a worked example of connecting campaign data to CRM outcomes, see the franchise marketing agency case study: 10 brands in one reporting system, with advertising connected to CRM deal stages.
Multi-touch attribution query examples
The queries below build a working rule-based model in BigQuery: paths, five models and a reconciliation check. They are illustrative. Your real schema depends on your sources, how you resolve identity and what counts as a conversion. Treat them as a pattern to adapt, not a drop-in build.
The example schema
Two tables in a dataset called mta. Each touchpoint belongs to a contact, and each conversion belongs to a contact. The path is built by joining them on contact_id inside a lookback window.
| Table | Column | Type | Meaning |
|---|---|---|---|
mta.touchpoints | touch_id | STRING | Unique ID for the interaction |
contact_id | STRING | The person or contact the touch belongs to | |
touch_ts | TIMESTAMP | When the touch happened | |
channel, source, medium, campaign | STRING | Normalized campaign fields | |
mta.conversions | conversion_id | STRING | Unique ID for the outcome |
contact_id | STRING | The same contact ID as the touches | |
converted_ts | TIMESTAMP | When the outcome happened | |
value | NUMERIC | Revenue or deal value credited by the model |
The rules in these examples: a 30-day lookback, touches at or before the conversion time, and no touch reused across a contact’s repeat conversions. Change them to suit your question, and write the change down.
Build paths within a lookback window
This table is the base for every model. It keeps one row per touch per conversion, with the touch’s position, the path length and how many days before the conversion it happened.
-- Eligible touches in the 30 days before each conversion, one row per touch per conversion.
CREATE OR REPLACE TABLE mta.paths AS
WITH touches AS (
  SELECT *
  FROM mta.touchpoints
  WHERE touch_ts IS NOT NULL
  QUALIFY ROW_NUMBER() OVER (PARTITION BY touch_id ORDER BY touch_ts) = 1  -- drop duplicate loads
),
convs AS (
  SELECT
    *,
    -- the contact's previous conversion, so one touch isn't reused across repeat purchases
    LAG(converted_ts) OVER (PARTITION BY contact_id ORDER BY converted_ts, conversion_id) AS prev_converted_ts
  FROM mta.conversions
)
SELECT
  c.conversion_id,
  CAST(c.value AS FLOAT64) AS conversion_value,
  t.touch_id,
  t.touch_ts,
  t.channel,
  t.source,
  t.medium,
  t.campaign,
  -- touch_id breaks ties when two touches share a timestamp, so positions are stable
  ROW_NUMBER() OVER (PARTITION BY c.conversion_id ORDER BY t.touch_ts, t.touch_id) AS touch_position,
  COUNT(*) OVER (PARTITION BY c.conversion_id) AS path_length,
  TIMESTAMP_DIFF(c.converted_ts, t.touch_ts, SECOND) / 86400 AS days_before_conversion
FROM convs AS c
JOIN touches AS t
  ON t.contact_id = c.contact_id
  AND t.touch_ts <= c.converted_ts
  AND t.touch_ts >= TIMESTAMP_SUB(c.converted_ts, INTERVAL 30 DAY)
  AND (c.prev_converted_ts IS NULL OR t.touch_ts > c.prev_converted_ts);
Three details matter here. Duplicate touch loads are dropped before the join, so they can’t inflate a path. touch_id breaks timestamp ties, so the same touch is always “first” on every rerun. And conversions with no eligible touch drop out of this table on purpose. The reconciliation check counts them as unassigned instead of hiding them.
First-touch and last-touch credit
-- All credit to the first touch, or all to the last touch.
SELECT
  channel,
  COUNTIF(touch_position = 1) AS first_touch_conversions,
  SUM(IF(touch_position = 1, conversion_value, 0)) AS first_touch_value,
  COUNTIF(touch_position = path_length) AS last_touch_conversions,
  SUM(IF(touch_position = path_length, conversion_value, 0)) AS last_touch_value
FROM mta.paths
GROUP BY channel
ORDER BY last_touch_value DESC;
Linear credit
-- Equal credit to every touch on the path.
SELECT
  channel,
  SUM(SAFE_DIVIDE(1, path_length)) AS linear_conversions,
  SUM(SAFE_DIVIDE(conversion_value, path_length)) AS linear_value
FROM mta.paths
GROUP BY channel
ORDER BY linear_value DESC;
linear_conversions is fractional. A channel that is one of four touches on four different paths gets 1.0 conversion, not 4.
Time-decay credit
The weight halves for every 7 days between the touch and the conversion. The weights are then scaled so each conversion still hands out exactly its own value.
-- More credit to touches closer to the conversion. Half-life: 7 days.
-- A touch 7 days out gets half the weight of one at conversion time; 14 days out, a quarter.
WITH weighted AS (
  SELECT
    conversion_id,
    channel,
    conversion_value,
    POW(0.5, days_before_conversion / 7) AS raw_weight
  FROM mta.paths
),
normalized AS (
  SELECT
    channel,
    conversion_value,
    -- scale the weights so each conversion's credit adds up to 1
    SAFE_DIVIDE(raw_weight, SUM(raw_weight) OVER (PARTITION BY conversion_id)) AS weight
  FROM weighted
)
SELECT
  channel,
  SUM(weight) AS time_decay_conversions,
  SUM(conversion_value * weight) AS time_decay_value
FROM normalized
GROUP BY channel
ORDER BY time_decay_value DESC;
A 7-day half-life suits short cycles. For a long B2B cycle, try a longer one and compare. The half-life is a choice you should record next to the result.
Position-based credit (40/20/40)
-- Position-based (U-shaped) 40/20/40: 40% first, 40% last, 20% shared by the middle touches.
-- Short paths: one touch gets 100%, two touches get 50% each.
WITH weighted AS (
  SELECT
    channel,
    conversion_value,
    CASE
      WHEN path_length = 1 THEN 1.0
      WHEN path_length = 2 THEN 0.5
      WHEN touch_position = 1 OR touch_position = path_length THEN 0.4
      ELSE SAFE_DIVIDE(0.2, path_length - 2)
    END AS weight
  FROM mta.paths
)
SELECT
  channel,
  SUM(weight) AS position_based_conversions,
  SUM(conversion_value * weight) AS position_based_value
FROM weighted
GROUP BY channel
ORDER BY position_based_value DESC;
The short-path rules are the part people get wrong. Without them, one- and two-touch paths hand out less than their full value, and the totals quietly fall short.
Check that the credit reconciles
First, put every model’s weights in one table. Your reports read from this, so each channel chart uses the same paths.
-- One row per touch per conversion, with each model's share of the conversion.
CREATE OR REPLACE TABLE mta.touch_credit AS
SELECT
  conversion_id,
  touch_id,
  channel,
  source,
  medium,
  campaign,
  conversion_value,
  IF(touch_position = 1, 1.0, 0.0) AS w_first_touch,
  IF(touch_position = path_length, 1.0, 0.0) AS w_last_touch,
  SAFE_DIVIDE(1, path_length) AS w_linear,
  SAFE_DIVIDE(
    POW(0.5, days_before_conversion / 7),
    SUM(POW(0.5, days_before_conversion / 7)) OVER (PARTITION BY conversion_id)
  ) AS w_time_decay,
  CASE
    WHEN path_length = 1 THEN 1.0
    WHEN path_length = 2 THEN 0.5
    WHEN touch_position = 1 OR touch_position = path_length THEN 0.4
    ELSE SAFE_DIVIDE(0.2, path_length - 2)
  END AS w_position_based
FROM mta.paths;
Then check it. Each model must hand out exactly each conversion’s value, and the assigned total plus the unassigned value must match the source total.
-- Every model should hand out exactly each conversion's value: no more, no less.
WITH per_conversion AS (
  SELECT
    conversion_id,
    SUM(conversion_value * w_first_touch) AS first_touch,
    SUM(conversion_value * w_last_touch) AS last_touch,
    SUM(conversion_value * w_linear) AS linear,
    SUM(conversion_value * w_time_decay) AS time_decay,
    SUM(conversion_value * w_position_based) AS position_based
  FROM mta.touch_credit
  GROUP BY conversion_id
),
checked AS (
  SELECT
    c.conversion_id,
    CAST(c.value AS FLOAT64) AS value,
    p.* EXCEPT (conversion_id)
  FROM mta.conversions AS c
  LEFT JOIN per_conversion AS p USING (conversion_id)
)
SELECT
  COUNT(*) - COUNT(DISTINCT conversion_id) AS duplicate_conversion_rows,  -- must be 0
  COUNTIF(linear IS NULL) AS unassigned_conversions,                      -- no eligible touch
  COUNTIF(GREATEST(
    ABS(first_touch - value), ABS(last_touch - value), ABS(linear - value),
    ABS(time_decay - value), ABS(position_based - value)
  ) > 0.01) AS conversions_off_by_more_than_a_cent,                        -- must be 0
  SUM(value) AS source_total,
  SUM(IF(linear IS NULL, value, 0)) AS unassigned_value,
  -- each of these plus unassigned_value should equal source_total
  SUM(first_touch) AS first_touch_total,
  SUM(last_touch) AS last_touch_total,
  SUM(linear) AS linear_total,
  SUM(time_decay) AS time_decay_total,
  SUM(position_based) AS position_based_total
FROM checked;
Read the result before you share any chart:
duplicate_conversion_rowsandconversions_off_by_more_than_a_centshould be 0. If either isn’t, look for a join that duplicates rows.- Each model total plus
unassigned_valueshould equalsource_total. If one model is off and the others aren’t, its weights don’t sum to 1. - A rising
unassigned_conversionscount is a coverage problem, not a model problem. Report it next to the chart.
Run it in Claude or ChatGPT with Maven
If you have a Maven account, you can ask the same questions in plain English. Maven is MetricMaven’s connector. It puts your checked marketing data into Claude or ChatGPT through MCP, so the assistant answers from your numbers. See reporting in your AI tools.
Maven’s attribution runs on your web sessions. It credits web conversions and their revenue to channel, source, medium or campaign under first-touch, last-touch, last non-direct, linear, position-based (40/20/40) or time-decay. Three limits to know:
- It works on workspaces with raw web analytics events. A workspace connected through the GA4 Data API returns
WEB_EXPLORE_UNSUPPORTEDfor these operations. - Date ranges for attribution and journeys can be up to 366 days. The lookback can be up to 90 days, and the default is 30.
- Time decay uses a 7-day half-life unless you ask for another one.
Below are prompts you can paste, each with the call the assistant makes. Every Maven call takes target, operation, options and a context object that records your request. Before these, the assistant calls workspace with operation: "list" to get your workspace_id. Field names are from the Maven MCP reference.
1. Compare two models by channel
“Compare last-touch and linear credit by channel for the last 90 days.”
Tool: query_metrics
{
  "target": {"workspace_id": "<workspace_id from workspace list>"},
  "operation": "attribution",
  "options": {
    "date_range": {"last": 90, "unit": "days"},
    "models": ["last_touch", "linear"],
    "group_by": ["channel"]
  },
  "context": {
    "user_request": "Compare last-touch and linear credit by channel for the last 90 days.",
    "agent_goal": "Credit key-event conversions and revenue to channels under last-touch and linear for the last 90 days.",
    "turn_id": "turn_01JBMTA0001",
    "fidelity": "exact"
  }
}
2. Find the campaigns that gain the most credit
“Which campaigns gain the most credit under position-based compared with last-touch? Use Q3 2026.”
Tool: query_metrics
{
  "target": {"workspace_id": "<workspace_id from workspace list>"},
  "operation": "attribution",
  "options": {
    "date_range": {"start": "2026-07-01", "end": "2026-09-30"},
    "models": ["last_touch", "position_based"],
    "group_by": ["campaign"],
    "limit": 50
  },
  "context": {
    "user_request": "Which campaigns gain the most credit under position-based compared with last-touch? Use Q3 2026.",
    "agent_goal": "Get campaign credit under last-touch and position-based for Q3 2026, to rank the gap between them.",
    "turn_id": "turn_01JBMTA0002",
    "fidelity": "exact"
  }
}
The assistant asks for both models in one call, then ranks the campaigns by the difference between them.
3. See how many sessions it takes to convert
“How many sessions does it take people to book a demo, and which channel sequences come before it? Last 90 days.”
Tool: query_metrics
{
  "target": {"workspace_id": "<workspace_id from workspace list>"},
  "operation": "journey",
  "options": {
    "date_range": {"last": 90, "unit": "days"},
    "conversion": {"type": "event", "event_name": "book_demo"},
    "touch_dimension": "channel",
    "sequence_length": 5,
    "top_n": 10
  },
  "context": {
    "user_request": "How many sessions does it take people to book a demo, and which channel sequences come before it? Last 90 days.",
    "agent_goal": "Get sessions-to-convert, time-to-convert and the top channel sequences before the book_demo event.",
    "turn_id": "turn_01JBMTA0003",
    "fidelity": "exact"
  }
}
journey returns the sessions-to-convert and time-to-convert distributions and the most common touch sequences. Use your own conversion event name. If your key events are already defined, you can leave conversion out.
4. Test a different half-life
“Rerun the linear vs time-decay comparison by source / medium for the last 6 months, with a 3-day half-life and a 60-day lookback.”
Tool: query_metrics
{
  "target": {"workspace_id": "<workspace_id from workspace list>"},
  "operation": "attribution",
  "options": {
    "date_range": {"last": 6, "unit": "months"},
    "models": ["linear", "time_decay"],
    "group_by": ["source_medium"],
    "half_life_days": 3,
    "lookback_days": 60
  },
  "context": {
    "user_request": "Rerun the linear vs time-decay comparison by source / medium for the last 6 months, with a 3-day half-life and a 60-day lookback.",
    "agent_goal": "Compare linear and time-decay credit by source / medium with a 3-day half-life and a 60-day lookback.",
    "turn_id": "turn_01JBMTA0004",
    "fidelity": "exact"
  }
}
Changing the half-life or lookback changes the answer. Ask the assistant to state both next to any number it gives you.
Common failure points
Most attribution reports that nobody trusts fail in the same few places. None of them is fixed by switching models.
- The outcome isn’t defined. “Conversions” means a form fill in one report and a won deal in another, with different date fields. Agree on one outcome and one date first.
- Tagging is inconsistent. If campaign tags vary, channel classification varies, and so does every model built on it.
- Records are forced together. Matching unrelated records to make journeys look complete produces confident numbers that aren’t real. Keep unmatched outcomes visible.
- Joins duplicate value. A many-to-many join can make credit add up to more than the source total while the chart still looks plausible. Reconcile before you report.
- Modeled data isn’t labeled. Estimated events mixed into observed totals make the report impossible to check.
- Late updates aren’t rerun. CRM records change after the fact. A report that never reprocesses old periods drifts away from the source.
- The model is undocumented. Without the lookback window and eligibility rules, nobody can reproduce or defend the number.
- Attribution is read as cause. MTA can show that a channel tends to appear early in paths that convert. It can’t show incremental impact on its own. When the decision needs a causal answer, use experiments and other business evidence.
If the data isn’t ready for any of this, start with the gaps in collection and reporting definitions. The tracking audit checklist shows what that work looks like over 30 and 60 days.
Related reading: Why your numbers never match between platforms, the marketing tracking audit checklist, with a 30/60-day example scope, and the guide to choosing an attribution model.
Part of: Why your numbers don’t match.
Get the next one before it hits.
Short emails when Meta, Google, GA4 or LinkedIn change something that moves your numbers.
Part of: Why your numbers don't match
Also in When the gap is attribution: Offline conversions: what they are, how to measure them, and what changed in 2026, GA4 multi-touch attribution without BigQuery: what the built-in reports can and can’t do, GA4 multi-touch attribution in BigQuery: build a custom attribution model in SQL
Frequently asked questions
What is multi-touch attribution?
Multi-touch attribution assigns credit for an outcome across the eligible interactions on a recorded path, instead of giving it all to one touch. It describes observed paths. It does not establish causality on its own.
What is an attribution model in marketing?
An attribution model is the rule or method that decides how credit for a conversion is shared across the touches before it. First-touch, last-touch, linear, time decay, position-based and data-driven are the common ones. The journey stays the same; only the allocation changes.
Which attribution model should I choose?
Pick the model that fits the reporting question. First-touch suits growing awareness or entering a new market. Last-touch suits short cycles with one or two touches. Linear or time decay suits long B2B journeys. If you use a platform’s data-driven model, compare it with a simpler rule and note the assumptions.
What are the limitations of attribution models?
Every model has a blind spot. First-touch ignores what closed the deal, last-touch over-credits brand and bottom-funnel activity, and linear treats a glance like a sales demo. All of them are limited to what your systems recorded and connected. No model is neutral.
What is the difference between deterministic and probabilistic attribution?
Deterministic attribution connects touches to outcomes with a documented identifier, such as an event ID or a CRM contact ID. Probabilistic attribution infers or estimates connections it can’t observe directly. Keep them separate and label modeled output.
Does attribution reporting include modeled data?
Sometimes. Some platforms supplement observed events with modeled key events when they can’t observe them directly, and Google documents that these may appear in eligible GA4 reports. Label modeled output and keep estimates separate from observed events.
Is multi-touch attribution only for large companies?
No. It’s most useful when a team has enough touchpoints and conversions to make journey-level analysis meaningful. Smaller teams can start with simple models before moving to warehouse-backed MTA.
Do I need complex software to use MTA?
Not at first. Many teams can begin with GA4, ad platform data, CRM data and a clear reporting model. Teams that need more control usually move MTA into BigQuery or another warehouse.
What does an MTA data pipeline include?
Five layers: raw ingestion keeps source records, normalization standardizes fields, identity and paths connect eligible interactions to outcomes, attribution applies versioned credit rules, and reporting shows the agreed metrics and their limits.
How do I check that MTA credit reconciles?
For each eligible outcome, the fractional credits should add up to the intended total. Across outcomes, allocated value plus any explicitly unassigned value should match the source total under the same definitions.
Is MTA better than marketing mix modeling (MMM)?
They answer different questions. MTA looks at user-level journeys and touchpoints. MMM estimates channel impact at an aggregate level. Mature teams often use both.
Does MTA work without third-party cookies?
It can, but it needs stronger first-party data, consent-aware tracking, server-side tagging, CRM joins and careful modeling assumptions.